Community journal

The latest from the MySQL community

Ideas, releases, practical guides, and perspectives from the people building with MySQL.

Follow the feed
Showing entries 571 to 580 of 998 « Previous | Next »
Displaying posts with tag: Performance (reset)
random poking

These are some of my notes from some sysbench in-memory r/o testing in past day or so:

  • At ‘fetch data by primary key’ benchmark with separate read snapshots at each statement, MySQL shines until ~200 concurrent threads, then performance starts dropping slightly faster than one would want, I think mostly from table cache LOCK_open contention
  • auto-commit cost (establishing read snapshot per statement) for SELECTs is ~10% for MySQL, but for PG it can be +50% in plain SQL mode and +130% (!!!!!!!) when using prepared statements (this can be seen in a graph – obviously the global …
[Read more]
DiskPageBufferMemory tuning and disk data statistics in MySQL Cluster 7.1.9

From MySQL Cluster 7.1.9 (not yet released) it is possible to get better stats on disk data tables. In fact, the statistics makes it possible to tune the DiskPageBufferMemory parameter (similar to innodb_bufferpool), in order to avoid disk seeks. It is much (understatement) faster to fetch data from the DiskPageBufferMemory than disk.

Here is an example/tutorial how to use this information and how to check the hit ratio of the DiskPageBufferMemory. Next time, I will explain about other counters you can get from ndbinfo.diskpagebuffer.

Finally, no more educated guesswork is needed.

Let's take an example.

I have a table t1 with 650000 record

CREATE TABLE `t1` (
`id` bigint(20) NOT NULL AUTO_INCREMENT,
`data1` varchar(512) DEFAULT NULL,
`data2` varchar(512) DEFAULT NULL,
PRIMARY KEY (`id`)
) …
[Read more]
MySQL Paginated displays – How to kill performance vs How to improve performance!

Pagination is used very frequently in many websites, be it search results or most popular posts they are seen everywhere. But the way how it is typically implemented is naive and prone to performance degradation. In this article I attempt on explaining the performance implications of poorly designed pagination implementation. I have also analyzed how Google, Yahoo and Facebook handle pagination implementation. Then finally i present my suggestion which will greatly improve the performance related to pagination.

Pushed down JOINs - Webinar

On Thursday, November 04, at 0900PST/1700CET/1600GMT there is a webinar about Pushed Down Joins. This webinar will explain how Pushed Down Joins works, and some performance numbers.
Register here: http://mysql.com/news-and-events/web-seminars/display-583.html.

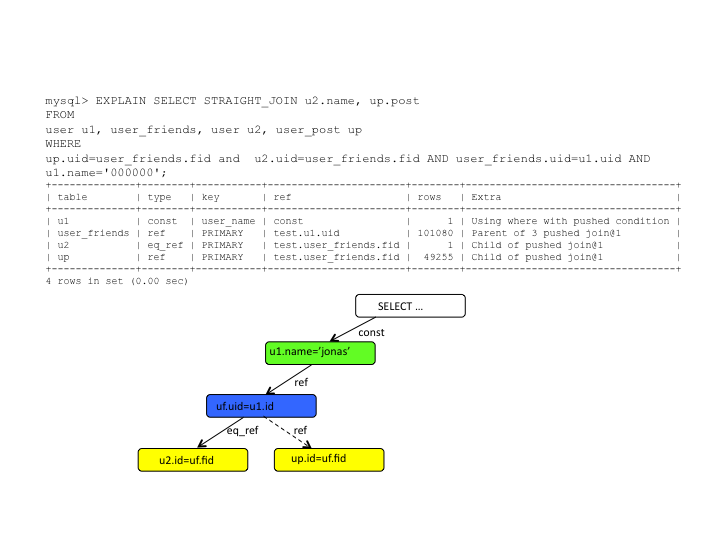
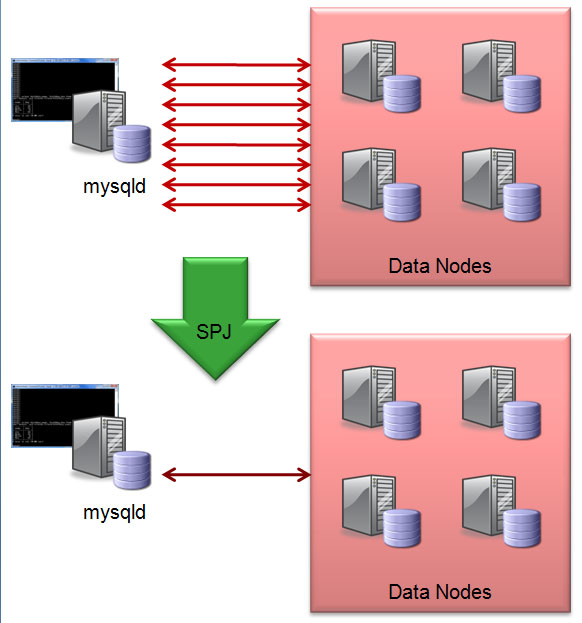
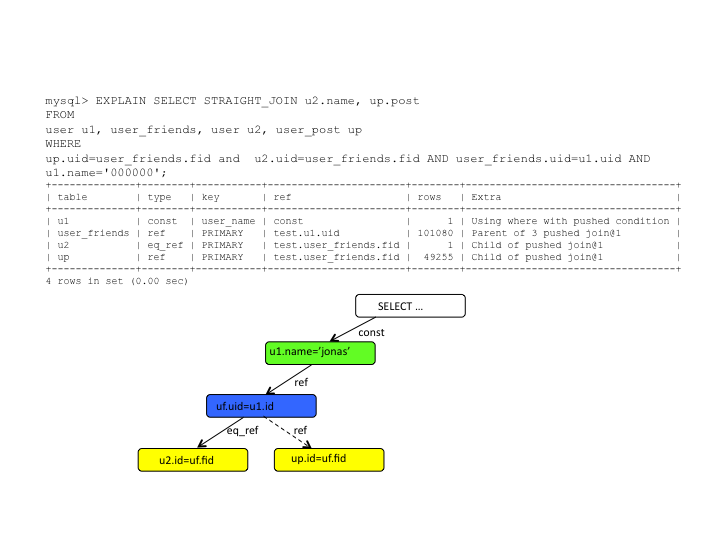
NDB Pushed JOINs means query shipping instead of data shipping and it reduces drastically the network hops between the MySQL Server and data nodes, which in turn gives a tremendous performance improvement. For particular queries a 180x improvement has been measured.

Impact of the sort buffer size in MySQL

The parameter sort_buffer_size is one the MySQL parameters that is far from obvious to adjust. It is a per session buffer that is allocated every time it is needed. The problem with the sort buffer comes from the way Linux allocates memory. Monty Taylor (here) have described the underlying issue in detail, but basically above 256kB the behavior changes and becomes slower. After reading a post from Ronald Bradford (here), I decide to verify and benchmark performance while varying the size of the sort_buffer. It is my understanding that the sort_buffer is used when no index are available to help the sorting so I created a MyISAM table with one char column without an index:

PLAIN TEXT CODE:

[Read more]
Glimpse of the future – massively improved JOIN performance for MySQL Cluster

MySQL Cluster Push-Down Joins

A great chance to find out about the “SPJ” project that’s under way to improve the performance of complex table JOINs. A free webinar has been scheduled for Thursday, November 04 at 09:00 Pacific time (16:00 UK; 17:00 Central European Time) – just register for the webinar at mysql.com. Even if you can’t attend, by registering you’ll get an email telling you where to watch the replay shortly after the webinar.

MySQL Cluster performance has always been extremely high and scalable when the work load is primarily primary key reads and write but complex JOINS (many tables in the JOIN and/or a large number of results from the first part of the query) have traditionally been much slower than when using …

[Read more]
MySQL Cluster - Performance (UPDATE on PK) - >120K tx/sec

This post follows on the previous post on SELECT performance. In this post I want to show three things:

  1. How many single row UPDATEs per second you can do on on a Cluster with two data nodes (updating 64B data by the PRIMARY KEY, no batching)
  2. Show how MySQL Cluster scales with threads and mysql servers
  3. How ndb_cluster_connection_pool affects performance

Next post will be what happens to INSERTs.

Setup

  • two data nodes
  • one to four mysql servers
  • interconnected with Gig-E (single NIC)

deployed on six computers (of varying quality, but not really modern, see below). www.severalnines.com/bencher was co-located with each mysql …

[Read more]
MySQL Cluster - Performance (UPDATE on PK) - >120K updates/sec

This post follows on the previous post on SELECT performance. In this post I want to show three things:

  1. How many single row UPDATEs per second you can do on on a Cluster with two data nodes (updating 64B data by the PRIMARY KEY, no batching)
  2. Show how MySQL Cluster scales with threads and mysql servers
  3. How ndb_cluster_connection_pool affects performance

Next post will be what happens to INSERTs.

Setup

  • two data nodes
  • one to four mysql servers
  • interconnected with Gig-E (single NIC)

deployed on six computers (of varying quality, but not really modern, see below). www.severalnines.com/bencher was co-located with each mysql …

[Read more]
Optimizing the MySQL IN() Comparison Operations Which Include the Indexed Field

The MySQL IN() Comparison Operator is said to be very quick if all the values are constants (the values are then evaluated and sorted first, and the search is done using a binary search). However, what if the field which the IN clause refers to, is part of the index used to execute the query? […]

Dynamic linking costs two cycles

It turns out that the overhead of dynamic linking on Linux amd64 is 2 CPU cycles per cross-module call. I usually take forever to get to the point in my writing, so I thought I would change this for once :-)

In MySQL, there has been a historical tendency to favour static linking, in part because to avoid the overhead (in execution efficiency) associated with dynamic linking. However, on modern systems there are also very serious drawbacks when using static linking.

The particular issue that inspired this article is that I was working on MWL#74, building a proper shared libmysqld.so library for the MariaDB embedded server. The lack of a proper libmysqld.so in MySQL and MariaDB has caused no end of grief for packaging Amarok for the various Linux distributions. My patch …

[Read more]